Streamhouse
The Streamhouse use case provides a real-time, production-native, and decentralized data architecture that keeps the continuously current state of a business available to production applications, analytics, and AI agents.
Category Definition
Streamhouse is an open, vendor-neutral category for data architectures that empower organizations to capture, transport, transform, govern, and serve data in motion at production service levels. IBM delivers the complete Streamhouse architecture through IBM Confluent.
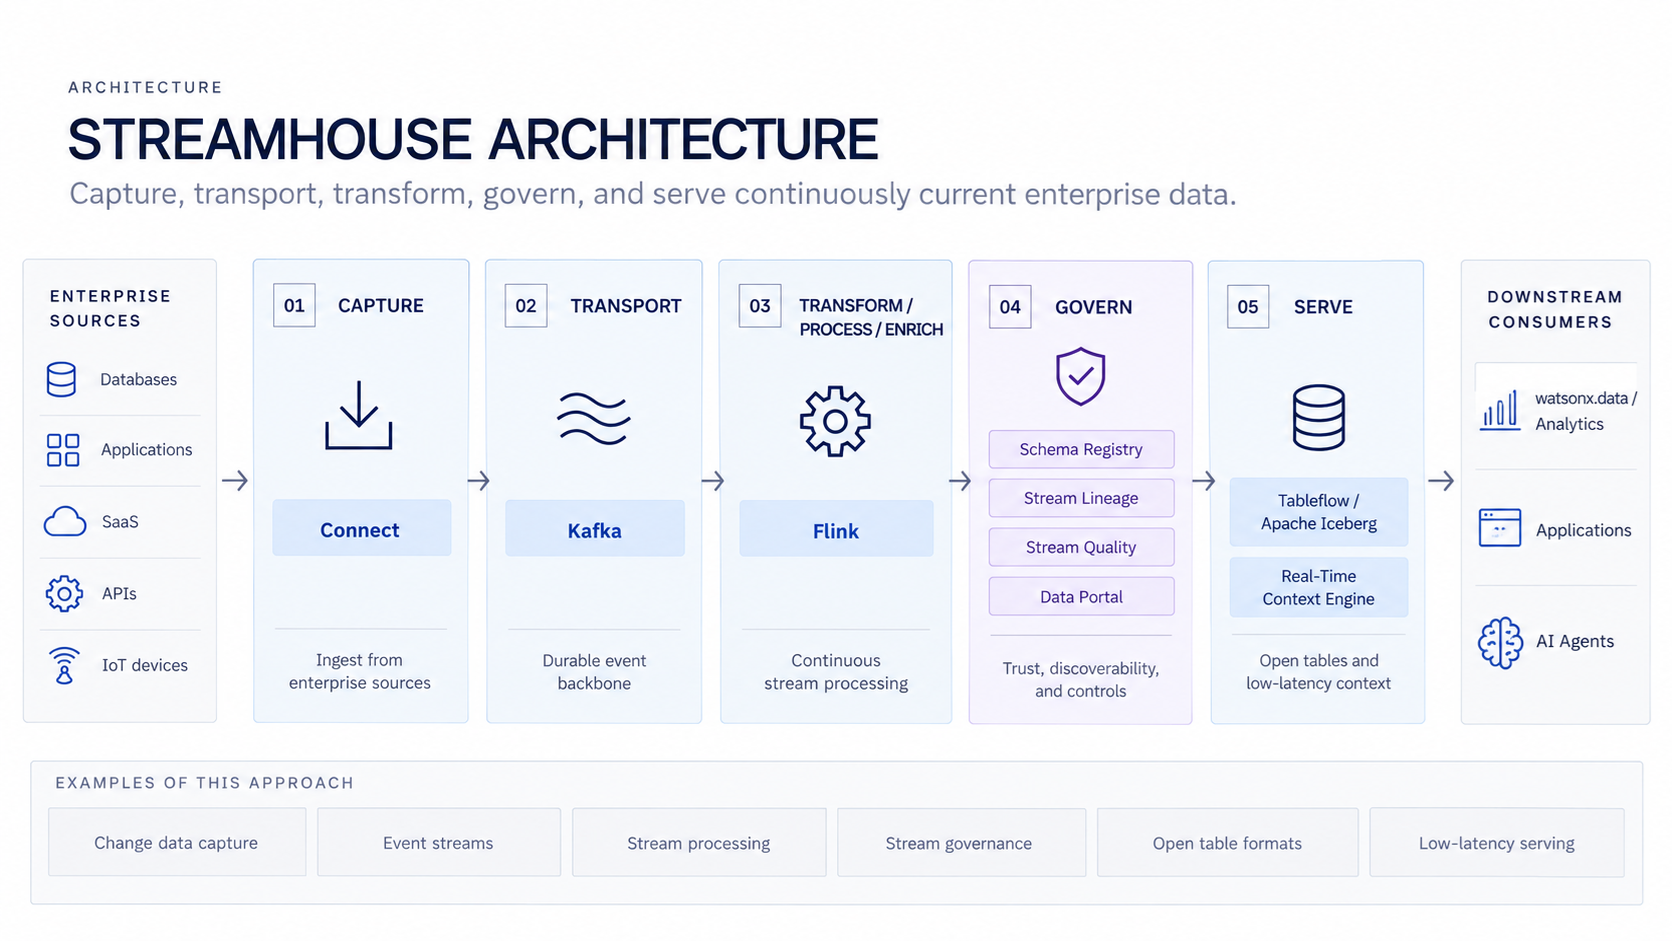
Available Building Blocks
| Capability | Products | Best Fit |
|---|---|---|
| Stream | IBM Confluent — Connectors & Kafka | Capture and transport enterprise event streams from databases, SaaS, IoT, and applications |
| Transform | IBM Confluent (Flink) | Real-time stream processing, stateful computation, windowing, filtering, and event enrichment |
| Govern | IBM Confluent — Stream Governance | Enforce schema contracts, end-to-end stream lineage, data quality rules, and catalog discovery |
| Serve | IBM Confluent — RTCE & Tableflow | Expose live state to AI agents via Real-Time Context Engine (MCP/REST) and open Iceberg tables for lakehouse analytics |
Business Value
Why Streamhouse matters
- Real-time freshness — data remains continuously current as business events occur, replacing stale batch snapshots.
- Production-native reliability — engineered to mission-critical SLAs so production applications and autonomous AI agents can depend on it continuously.
- Decentralized data access — meets data where it already lives across databases, applications, cloud services, and edge devices.
- Single stream for ops and analytics — powers both real-time operational applications and open-table lakehouse analytics without redundant ETL pipelines.
- Governed and trustworthy AI context — grounds AI agents in live operational facts with strict data contracts and end-to-end lineage.
When to Use
| Scenario | Recommended Building Block |
|---|---|
| Ingesting CDC from databases, SaaS, mainframes, or IoT feeds into durable event streams | Stream |
| Filtering, aggregating, or joining high-volume streams continuously in motion | Transform |
| Enforcing schema compatibility, tracking stream lineage, and setting data quality contracts | Govern |
| Delivering low-latency live state to AI agents via MCP/REST or streaming to Apache Iceberg tables | Serve |
Reference Architecture
flowchart LR
    SRC["Enterprise Data Sources<br/>Databases · SaaS · IoT · Applications"]

    subgraph STREAMHOUSE["Streamhouse Architecture (IBM Confluent)"]
        direction LR
        subgraph CAPTURE_TRANSPORT["Capture & Transport"]
            CONNECT["Confluent Connect"] --> KAFKA["Apache Kafka Topics"]
        end

        subgraph TRANSFORM["Transform"]
            KAFKA --> FLINK["Apache Flink SQL"]
        end

        subgraph GOVERN["Govern"]
            SR["Schema Registry"]
            SL["Stream Lineage"]
            SQ["Stream Quality"]
            DP["Data Portal"]
        end

        subgraph SERVE["Serve"]
            RTCE["Real-Time Context Engine<br/>(MCP / REST)"]
            TABLEFLOW["Tableflow / Iceberg Sink"]
        end

        FLINK --> GOVERN
        GOVERN --> SERVE
    end

    SRC --> CONNECT
    RTCE --> AGENTS["AI Agents / Watsonx Orchestrate<br/>Operational Applications"]
    TABLEFLOW --> LAKEHOUSE["IBM watsonx.data Lakehouse<br/>(Presto / Spark / Iceberg)"]
IBM Products Used
| Product | Role in Streamhouse |
|---|---|
| IBM Confluent | Complete managed Streamhouse platform delivering Connectors, Kafka, Apache Flink, Stream Governance, Tableflow, and Real-Time Context Engine |