Bob+ Skills and Modes – Data
IBM Bob ships with purpose-built Skills and Custom Modes for every Data building block, giving engineers an AI-assisted workflow to plan, build, configure, and operate real-time streaming, stream processing, integration pipelines, lakehouse analytics, and vector retrieval directly from their IDE.
How to install the Skills
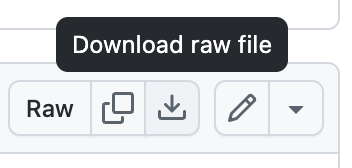
The Skills have been packed into a single .zip that you can easily download and install. Go to the skills.zip page and click the Download raw file icon at the upper-right of the page. Copy all skill folders at either the global, ~/.bob/skills, or project-level, <project>/.bob/skills.
Skill Taxonomy
Each Skill for IBM Building Blocks often aligns with an IBM product but not always. For specifics on how each skill works, read through the associated SKILL.md.
 Data Skills |
|---|
 Streamhouse |
Data-streaming: Confluent
Works with IBM Confluent for real-time data streaming, Kafka topic management, Schema Registry contracts, stream processing configuration, and event pipeline setup.
Data-streaming: Confluent plus Terraform
Expert guidance for building real-time streaming systems on Confluent Cloud using Infrastructure-as-Code (Terraform), Apache Flink SQL, and Python producers.
Streamhouse Continuous RAG
Combines Real-Time live operational state with RAG enterprise knowledge — design and implement continuous RAG pipelines that keep AI agents grounded in live context.
|
 Pipelines |
RAG Pipeline Builder
Complete RAG pipeline design — IBM watsonx.ai embedding integration, OpenSearch HNSW + hybrid search design, chunking strategy selection, and evaluation with RAGAS metrics.
RAG MCP Server Builder
MCP server development (SSE transport, FastMCP), RAG ingestion + retrieval tool design, IBM Bob / Claude integration, and deployment to IBM Code Engine.
Data Ingestion: Unstructured (UDI + Docling)
IBM Docling document parsing, UDI pipeline configuration, multi-format chunking (PDF, DOCX, HTML, images), metadata extraction, and Python automation scripts.
Data Ingestion: UDI + OpenSearch
IBM UDI + OpenSearch integration, document search pipeline setup, and OpenSearch index provisioning for UDI output into IBM watsonx.data.
Text2SQL: Metadata Enrichment
watsonx.data Intelligence project onboarding, table/column description enrichment, synonym design, query example authoring, and accuracy measurement.
Text2SQL: Query Optimizer
Model selection, SQL safety validation, accuracy evaluation (exact-match + execution accuracy), error pattern diagnosis, and SQL dialect tuning.
Data Ingestion: Structured (DataStage)
IBM DataStage connector config, CDC pipeline design, schema mapping, batch and incremental load strategies into IBM watsonx.data lakehouse tables.
|
 Lakehouse |
Data Quality: Rules
Data quality rule authoring, watsonx.data Intelligence quality checks, profiling automation, threshold design, and compliance reporting patterns for AI-ready data.
Data Lineage: OpenLineage Instrumentation
OpenLineage event design, Python/DataStage/Spark instrumentation patterns, IBM Databand lineage API integration, and lineage graph authoring.
Data Observability: Databand Pipeline Setup
IBM Databand pipeline onboarding, OpenLineage event design (START / COMPLETE / FAIL), alert policy authoring (null-rate, schema-drift, SLA-breach), and IAM auth patterns.
Zero-Copy Lakehouse
Presto SQL optimization, Spark job configuration on watsonx.data, cross-catalog federation design, and Iceberg table maintenance.
Vector Search: AstraDB
Astra DB vector collection creation, IBM watsonx.ai embedding integration, ANN cosine search queries via `astrapy` Data API, and metadata filtering.
Vector Search: OpenSearch
IBM watsonx.data OpenSearch k-NN index design, HNSW parameter tuning (`ef_construction`, `m`), and hybrid search (vector + BM25) score fusion.
|
Data Modes
Instructions and related files for these custom modes can be found in their respective repository.
Data Modes
|
|---|
Streamhouse |
Data Ingestion
AI-generated data pipeline mode for streaming (Kafka / Flink), CDC, and structured/unstructured sources. Describe your data source and target — Bob generates the complete pipeline automatically.
|
Pipelines |
Text-to-SQL
Natural language to SQL using IBM watsonx.data Intelligence Text2SQL API. Bob helps build the FastAPI application, enrich database metadata (table/column descriptions, synonyms), and evaluate SQL accuracy across Presto, PostgreSQL, Oracle, and Snowflake dialects.
RAG Builder
End-to-end RAG architect — pipeline architecture, hybrid search design, chunking strategy, IBM watsonx.ai embedding model choice, MCP server design, and RAG evaluation (RAGAS).
RAG Ingestion Builder
Focused ingestion specialist — IBM COS document loading, chunking, watsonx.ai embedding, OpenSearch indexing, and MCP ingestion tool design (`ingest_from_cos`).
RAG Retrieval Builder
Focused retrieval and generation specialist — hybrid search queries, reranking, watsonx.ai Granite generation, RAGAS evaluation, streaming SSE responses, and MCP retrieval tools.
|
Lakehouse |
Data Lineage Builder
End-to-end lineage tracking with IBM Manta and watsonx.data Intelligence. Bob assists with OpenLineage instrumentation, impact analysis, compliance reporting, and lineage visualization.
Data Quality Builder
Data quality rule authoring and monitoring with watsonx.data Intelligence. Bob helps define validation rules, configure profiling, set quality thresholds, and build compliance reports.
Data Observability Builder
IBM Databand pipeline onboarding, OpenLineage instrumentation for Python/DataStage/Spark, alert policy design, and quality threshold tuning.
OpenSearch Builder
IBM watsonx.data OpenSearch k-NN index design, HNSW parameter tuning, hybrid search score fusion, and IBM watsonx.ai embedding integration.
Astra DB Vector Builder
DataStax Astra DB vector collection design, `astrapy` ANN search patterns, IBM watsonx.ai embedding integration, and IBM COS ingestion for serverless global vector storage.
|
For the complete list of all Building Block skills across AI, Data, and Automation, see the Bob+ Skills page.